How I Tell a Machine I Cannot Reach What to Do and Know When It Is Done
On this page
- Introduction
- A. Work on a machine that cannot be called
- B. What a broker is, and why silence is the enemy
- C. Six obstacles in the way
- Method
- A. Both sides dial out
- B. One key, two parsers
- C. A status that outlives its sender
- D. The limit that was announced, and the one that was enforced
- E. The exception nobody saw
- F. How waiting for delivery can break delivery
- Results and Discussion
- A. What the six decisions add up to
- B. Silence is not an answer
- C. What this does not cover
- Conclusion
- Terms
Introduction
A. Work on a machine that cannot be called
My laptop's GPU has 4 GB of video memory, or VRAM — the memory a model must fit into to run on the GPU. That rules out the heaviest part of several of my projects — generating images with SDXL, synthesising narration with a large speech model — so that part runs on a Google Colab runtime instead — a virtual machine Google lends for the length of a session — with a T4 GPU and about 15 GB of VRAM. The laptop keeps everything else: the preparation, the review, and a browser interface from which I decide what gets generated next.
That split creates a problem that has nothing to do with GPUs. The interface is on the laptop; the worker that does the generating is in Colab. The interface has to tell the worker what to do — start this project, redo that image, stop — and it has to find out what the worker is doing: which item is running, which finished, whether the worker is even alive.
The obvious way to do that is to call the worker directly. And the worker cannot be called. A Colab runtime has no stable address, no port that can be opened to the outside, and a lifetime measured in hours. It can make outbound connections to anywhere, but nothing outside can start a conversation with it.
The challenge is to tell a machine I cannot reach what to do, and to know when it has done it.
The second half of that sentence turned out to be the hard half. Sending an instruction is simple once there is a channel. Knowing — knowing that the worker is alive, that the instruction arrived exactly once, that the absence of news means "still working" rather than "died an hour ago" — is where nearly every obstacle below came from.
Easy to state, awkward to build. Almost everything that can go wrong here goes wrong silently: a status that stays true after its sender dies, a failure swallowed on a background thread, a limit announced as one number and enforced as another.
B. What a broker is, and why silence is the enemy
The channel that made this work is a message broker speaking MQTT. A broker is a small server that both sides connect to. Neither side needs to be reachable, because both dial out. One side publishes a message on a named topic; every client subscribed to that topic receives it. The interface publishes commands and subscribes to status; the worker does the opposite.
Two features of MQTT carry most of the weight here, and both are worth defining before they appear. A retained message is one the broker keeps and hands to anyone who subscribes later, so an interface opened five minutes after the worker announced itself still learns the announcement. A Last Will is a message a client registers when it connects, which the broker publishes on the client's behalf if the connection drops without a clean goodbye. The two are designed to work together: a client announces itself with a retained message and registers a retained Last Will that contradicts it, so that whichever was published last is what a newcomer sees. As later sections show, that pairing covers less than it appears to.
The deeper point is about silence. In a direct call, no answer is itself an answer: the call failed. On a broker, no message means nothing at all. The worker might be busy, might be dead, might be sending messages that never arrive, might be receiving commands it has already carried out. Every obstacle below is a place where silence was ambiguous, and every decision below is a way of turning some kind of silence into a signal.
C. Six obstacles in the way
The worker is the one that cannot be reached. The usual shape — a client calling a server — runs the wrong way here. The first version put a web server inside the runtime and reached it through Colab's own port proxy, and Colab warned about and restricted that. Polling the shared storage for changes was the other rejected option: slow to notice anything, and wasteful while nothing happens.
Two languages read the same key differently. The worker is Python and the interface is TypeScript. Every item has a composite key, both sides parse it, and the same-looking line of code does different things in the two languages.
The last message a dead worker sent stays true forever. The worker announces that it is online as a retained message. If the runtime dies, nothing replaces it, and every interface opened afterwards is told the worker is alive.
A broker's advertised limit is not its real limit. The public broker announced one number for how many messages could be in flight at once. Measured, it accepted an eighth of that.
Failures on the network thread disappear. The MQTT library calls back into my code from its own thread, and an exception there is swallowed without a trace — taking with it the very first status message.
Waiting to confirm a message can stop messages arriving. A safeguard that confirmed every delivery ended up starving the connection, forcing reconnects — and each reconnect replayed every old command, so the worker spent hours redoing work it had already finished.
The order goes from the shape of the channel, through what the two ends must agree on, to what each end can and cannot know about the other. The last obstacle is the most expensive and the least obvious, because it combines three separate behaviours that are each harmless on their own.
Method
A. Both sides dial out
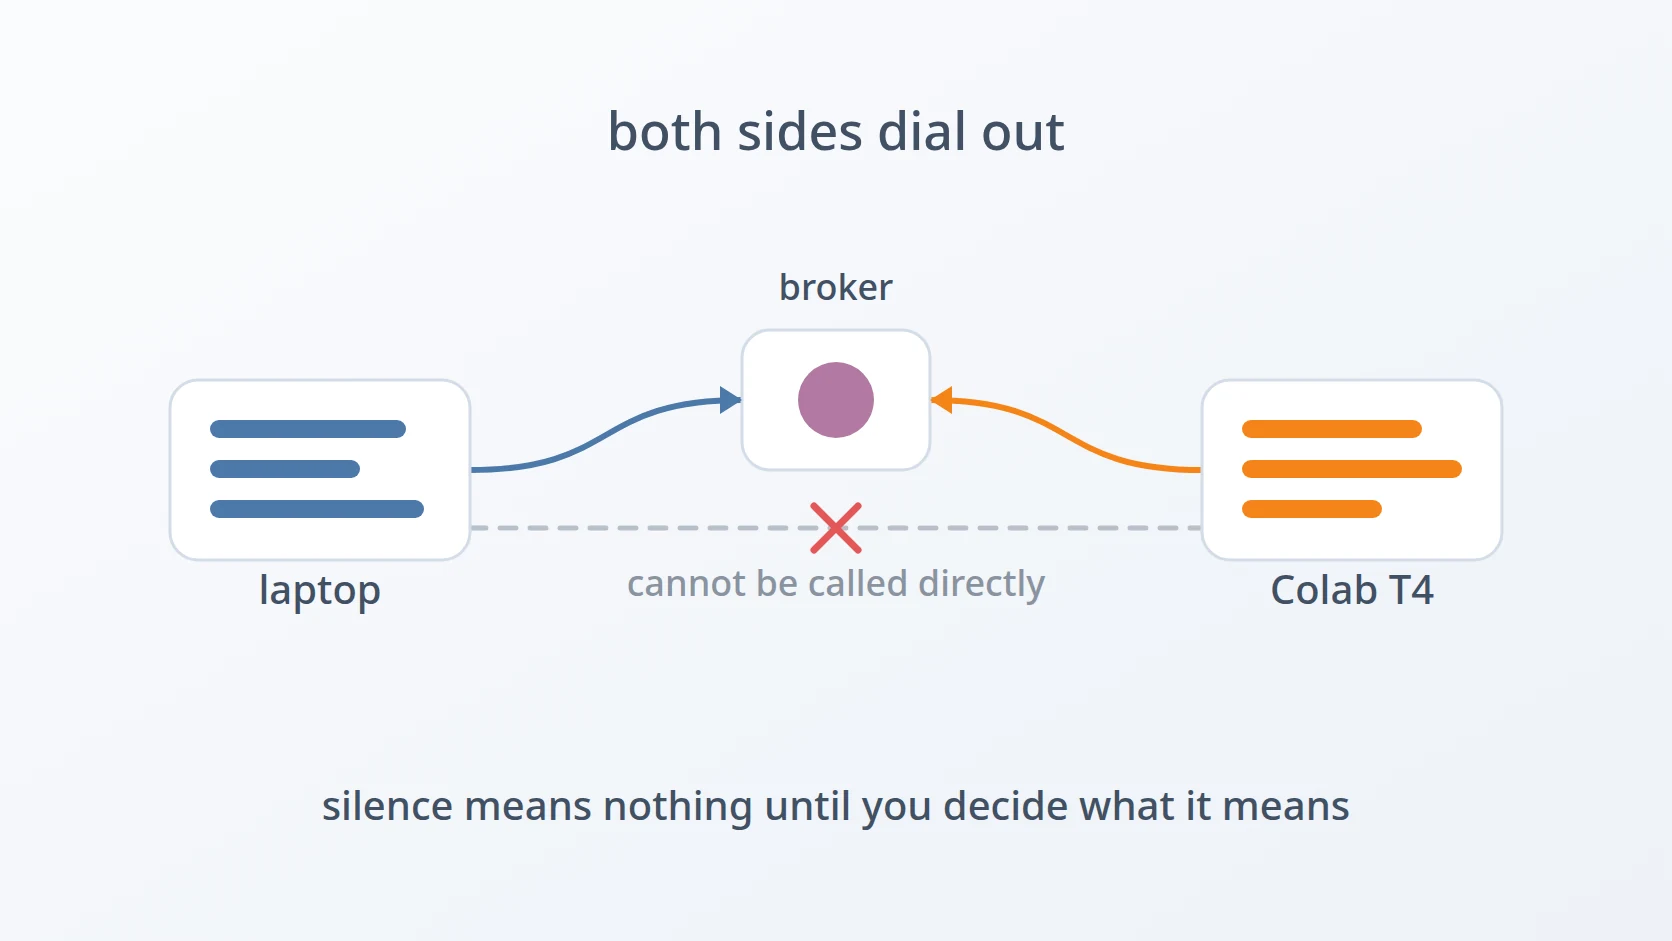
Here is the answer to the first obstacle: stop trying to reach the worker, and give both sides a third place to reach instead. The worker connects outward to the broker, exactly as the interface does:
Nothing on the Colab side needs to be reachable. The runtime makes one outbound connection and keeps it open, and everything else travels over it in both directions.
The broker itself was a public one, free and already running. That choice deserves an honest description: it meant nothing to install and nothing to maintain, which made it the right way to find out whether the design worked at all. It also had a property that turned out to be useful for testing. On a public broker, a fake worker publishing to the same topics is indistinguishable from the real one — so the whole interface could be built and verified against a small script pretending to be the worker, before the real worker existed.
Behind that choice sat the rejected alternative. The first version of this system served its interface from inside the Colab runtime and reached it through Colab's port proxy. Colab warned about and restricted that arrangement. Moving the interface onto the laptop and letting the worker become a pure worker — no web server, no pages, only a loop that listens and works — was what made the broker necessary in the first place.
B. One key, two parsers
This answers the second obstacle. Every item has a composite key such as shot:chapter:scene:index or obj:object:state. The worker parses keys in Python; the interface parses them in TypeScript. The natural move is to translate the Python line for line. That is exactly the move that fails:
# Python: the remainder is kept in the last field
# ['a', 'b', 'c:d']
# JavaScript: the remainder is thrown away
// The same method name, the same arguments, and a different meaning. Python's limit says how many splits to make; JavaScript's says how many pieces to keep. A state name containing a colon would arrive intact in the worker and truncated in the interface, and neither would complain.
So the interface rebuilds the Python behaviour explicitly instead of relying on the resemblance:
const rest = key.slice(4)
const i = rest.indexOf(':')
if (i <= 0) return null
const objectId = rest.slice(0, i)
const stateId = rest.slice(i + 1)   // the whole remainder, as split(":", 2) keeps it
The rule behind it is stricter than "match the output". The interface must reject exactly the keys the worker rejects. An interface more permissive than its worker displays items that no one will ever process, which is a silent failure of its own. The parser was checked against 2,148 keys — 2,131 real ones from a working project plus 17 edge cases — each compared with Python's own result. All matched.
C. A status that outlives its sender
This answers the third obstacle. The worker announces itself with a retained status message, so that an interface opened at any time learns immediately whether a worker exists. The flaw is in what happens when the runtime dies. Nothing publishes a correction. The retained message still says online: true, and it will say so to every subscriber, forever.
Three mechanisms close that gap, and each covers a case the others miss. The Last Will, registered at connect time, is a retained online: false that the broker publishes if the connection drops uncleanly. A heartbeat republishes the status every thirty seconds, even while idle:
= 30
continue # model still loading
The heartbeat skips its beats until the model has loaded. During loading the main thread holds Python's interpreter lock in long stretches, and a beat fired then only produces delivery warnings; the status for that period was already announced on connect, so nothing is lost by waiting.
And the interface judges every retained status by its own timestamp, rather than by the moment it arrived:
if (retained) {
  // a retained message is an old photo, not proof of life
  stale.value = Date.now() - (m.ts ?? 0) * 1000 > STALE_MS
} else {
  bump()
}
With STALE_MS at 90 seconds — three missed heartbeats — a retained message that is 204 seconds old is judged stale even though it says online: true. Crucially, a retained message does not refresh the staleness timer. Only live messages do. Without that rule, reopening the interface would reset the clock with the very message whose age is in question.
The heartbeat is also a consequence of that rule, and it is worth saying so plainly. Once only live messages count as proof of life, an idle worker that sends nothing is indistinguishable from a dead one. The heartbeat exists to keep an idle worker from being reported dead.
The interface turns all of this into four states rather than two, because each one asks for a different action: broker disconnected (check the network), worker dead (run the notebook), worker idle (press Start), worker busy (wait). The distinction between idle and busy matters most. Showing an idle worker in the same green as a busy one would leave people waiting for a run they had never started.
D. The limit that was announced, and the one that was enforced
This answers the fourth obstacle. MQTT lets a broker announce how many unacknowledged messages a client may have in flight. The public broker announced 32. Testing it directly gave a different answer:
# QoS 2 publishes in flight at once, same public broker
The number that governs behaviour is the measured one. And it matters, because a worker that publishes a progress update after every small step sends nearly two thousand near-identical messages in a single run. Against a limit of four in flight, that is a flood.
Progress updates were throttled to one every five seconds:
= 5.0
=
return
= The throttle is safe because of what progress is. It is a summary the interface can also recompute on its own by rescanning the store, so a dropped update makes the display late, never wrong. Per-item events — this one started, that one finished — are not throttled, because those are the ones the interface cannot reconstruct.
E. The exception nobody saw
This answers the fifth obstacle. When the worker connects, the MQTT library calls a function of mine, _on_connect, which publishes the worker's first status. It calls it from the library's own network thread, immediately after the connection opens.
Suppose that function reads a variable describing the loaded model. In a notebook, top-level code runs in order, and such a variable is defined further down — after the model has loaded. The callback then raises a NameError, and an exception raised inside the library's callback is swallowed without a message. The first retained status is never sent, and the interface reports the worker dead while it is busy loading an eleven-gigabyte model.
So the callback reads the value in a way that tolerates its absence:
: ,The more useful part is the test that has to catch it. A simulator runs the notebook's cells with the heavy libraries replaced by stubs, and a fake MQTT client that never calls on_connect would leave the callback unexercised, so deliberately reintroducing the fault would not make the test fail. The fake behaves like the real library in the one way that matters:
With that, reintroducing the fault fails the simulation, which is the only evidence that the simulation tests anything. A test that cannot fail proves nothing.
F. How waiting for delivery can break delivery
This answers the sixth obstacle, and it is the most expensive one. The symptom is a queue of regeneration requests that counts down and then stalls for hours, while the runtime stays alive and the GPU stays busy.
The GPU is busy redoing images that are already finished. Three behaviours combine to produce that, each harmless alone.
The first is a safeguard: each publish waiting up to five seconds to confirm delivery. In a PDF converter it does real good — without it, the main thread goes straight back into heavy work, the delivery handshake never completes, and the interface shows "0 of 11 done" while everything is finished. The same remedy in a worker where one image takes about eighty seconds does the opposite. The waiting happens on the thread that holds Python's global interpreter lock during generation, so the library's network thread starves, misses its sixty-second keepalive, and the broker drops the connection.
The second is a worker that reconnects with a persistent session. The broker keeps every command addressed to that session — every regeneration request — and on each reconnect it delivers them all again.
The third is that a regeneration command does exactly what it says. Receiving one again produces a new version, as it should. The worker is not confused; it is obeying commands it has already obeyed.
The evidence for this shape of failure is always in the log: a line announcing a connection that appears twice in the middle of one run, and "finished" lines that repeat. Counting the distinct ones against the hours spent shows how much of the GPU went to duplicates.
What closes it is one argument:
A clean start means the broker keeps no session, so a reconnect brings nothing old back with it. The interface uses a clean session as well, so both sides follow the same rule.
Two further decisions remove the reason for the reconnects. The publish path does not wait, while the library's return code is still checked. And the delivery guarantee is QoS 1, at least once, rather than QoS 2, exactly once — on both sides, as one contract. That is safe only because a duplicate status message is harmless: the interface judges messages by their content and timestamp, not by their count.
Results and Discussion
A. What the six decisions add up to
The interface now starts, stops, and redirects work on a machine it can never call, and it can tell apart the four situations that need different responses from me. The table lists the decisions against what they replaced.
| Decision | What it buys | Alternative rejected |
|---|---|---|
| broker both sides dial out to | the worker never needs to be reachable | web server inside Colab via its port proxy — restricted |
| public broker first | nothing to install; a fake worker can stand in for tests | building infrastructure before the design is proven |
| parser rebuilt, not translated | 2148 keys parse identically on both sides | copying the Python line into TypeScript |
| Last Will + 30 s heartbeat + 90 s staleness | a dead worker shows as dead; an idle one does not | trusting the retained online: true |
| progress at most every 5 s | 1867 messages per run reduced to a trickle | trusting the announced limit of 32 |
| simulator that fires callbacks | a callback bug fails the test | a fake client that never calls back |
| clean start, QoS 1, no blocking wait | no replayed commands, no starved connection | persistent session, QoS 2, wait on every publish |
B. Silence is not an answer
Lined up, the obstacles share one feature. In each, the absence of something was read as meaning something it did not.
No correction after online: true reads as "still online". No error from a callback reads as "the callback worked". No complaint from the broker below its announced limit reads as "within the limit". No error from the key parser reads as "parsed correctly". And no disconnect in the application's view reads as "no reconnects", while the session quietly replays hours of work.
Each fix turns a particular silence into a signal. A Last Will makes a disappearance audible. A heartbeat makes an idle worker distinguishable from a dead one. A timestamp makes an old message recognisable as old. A test that fires callbacks makes a swallowed exception visible. A clean session means a reconnect cannot bring back what was already done.
That is the general lesson, and it holds for message-based systems well beyond this one. When two parts of a system talk only through messages, there is no failure that announces itself — every failure looks like quiet. The design work is deciding, for each kind of quiet, what it should mean, and then making sure something speaks up when it means the other thing.
C. What this does not cover
Everything here ran on a public broker by choice, because the question at this stage was whether the design worked at all. A public broker has no identity and no access control, so anything handling private data or running unattended needs a broker with identities, access control, and encryption instead — a substantial piece of work with obstacles of its own.
It also assumes one worker per kind of work. Two workers picking up the same commands would need a way to divide them, and duplicate-tolerant messages would no longer be enough on their own.
Conclusion
A 4 GB GPU moved the heavy work of several projects onto a Colab runtime, and a Colab runtime cannot be called. A message broker solved the reachability problem in an afternoon: both sides dial out, and a topic replaces an address. Everything after that was about knowing — whether the worker is alive, whether a command arrived once, whether no news is good news.
The six obstacles are rarely loud. A retained status stays true after its sender dies. A callback fails and nothing says so. A broker enforces a limit an eighth the size of the one it announces. Two languages read one key two ways. And a safeguard copied from a project where it helps, combined with a persistent session, can cost hours of GPU time redoing finished work.
What carries over is a habit: for every silence in a message-based system, decide what it means, and give the other meaning a way to be heard.
Terms
- MQTT
- A lightweight publish/subscribe messaging protocol. Clients connect to a broker, publish messages to named topics, and receive messages from topics they subscribe to.
- retained message
- A message the broker stores and delivers to every client that subscribes to the topic later, so a newcomer learns the latest value immediately.
- Last Will
- A message a client registers when it connects. The broker publishes it on the client's behalf if the connection drops without a proper disconnect.
- QoS
- Quality of Service. Level 1 delivers a message at least once and may duplicate it; level 2 delivers exactly once at the cost of a four-step handshake per message.
- clean start
- A connection option telling the broker to discard any stored session for the client, so nothing queued during a previous connection is delivered again.
- GIL
- Python's global interpreter lock. Only one thread runs Python code at a time, so a thread holding it for long stretches can starve every other thread in the process.
Technologies covered
- Python
- TypeScript
- Google Colab
- EMQX
- MQTT



